How to Structure an Article for SEO: Markup and Platform Constraints
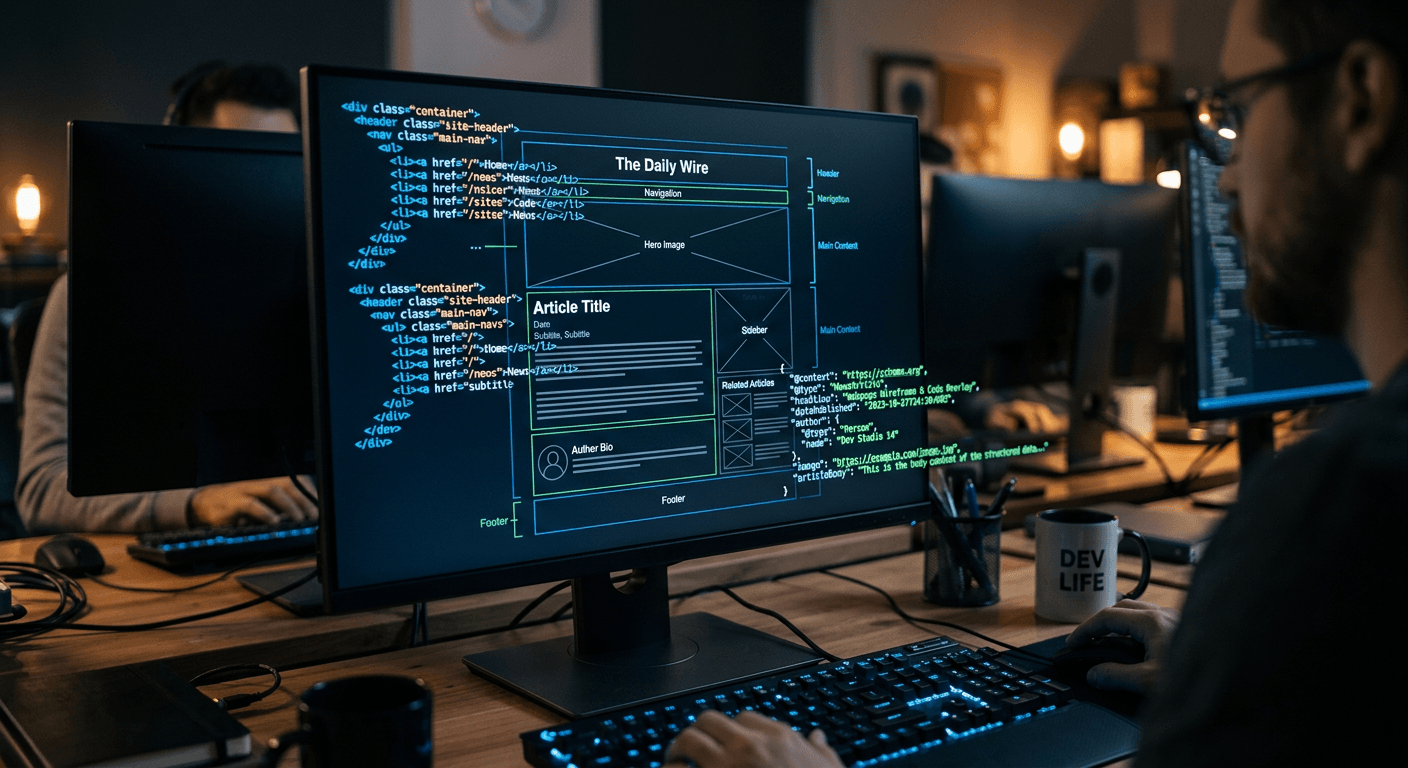
The most common misconception about technical content publishing is that search engines parse a page exactly as a human sees it on the screen. When planning an article for seo, technical marketers often obsess over visual keyword placement while entirely ignoring the Document Object Model (DOM) tree. Search bots strip away CSS styling immediately. They rely entirely on raw HTML semantics, JSON-LD scripts, and internal routing structures to determine what an entity is and how heavily it should be weighted. If your content looks like a definitive guide visually but renders as a flat wall of unmarked text elements to a crawler, the search engine will discard the hierarchy you thought you built.
Quick Summary
Structuring digital content requires engineering the underlying code rather than just styling the visible text. This dictates how search engines extract entities, map relevance, and assign indexing priority across complex architectures.
- Semantic HTML5 tags must replace visual styling for document outlines.
- Nested JSON-LD schema is required to disambiguate publisher and author entities.
- Internal link graphs determine indexing priority, overriding XML sitemap hints.
- Rigid CMS platforms require specific workarounds to manage rendering delays.
Table of Contents
- 1. Mapping an article for seo to the Document Object Model
- 2. Injecting schema markup for entity recognition
- 3. Aligning internal link routing with crawler priority
- 4. Adapting technical architecture to restrictive platforms
- Common Pitfalls & Troubleshooting
- FAQ
- Recommended Reads
1. Mapping an article for seo to the Document Object Model
Semantic HTML dictates crawler comprehension
The foundation of technical content structuring lies in the Document Object Model. Modern search engines map your HTML directly to an accessibility tree, evaluating the logical relationship between sections. A document must begin with a clear <main> wrapper, containing an <article> tag that isolates the primary content from navigation bars and footer widgets.
The mechanics of this mapping rely on strict heading hierarchy (H1 through H6). A crawler assumes that every H3 belongs logically to the H2 immediately preceding it. The fundamental error writers make here is selecting heading tags based on visual size rather than logical nesting. If your CMS theme formats an H4 to look like a pull quote, and you use it purely for that visual effect halfway through an H2 section, you fracture the logical outline of the document. The crawler registers a broken sub-section rather than a stylized quote.
To verify your structure, you must disable CSS in your browser and read the raw HTML sequence. The text should read like a strictly indented academic outline. Any element styled to look like a heading but wrapped in a generic <div> or <p> tag will be treated as standard body text, stripping it of any structural weight during the indexing phase.
2. Injecting schema markup for entity recognition
Disambiguation fails without nested JSON-LD
While HTML outlines the structure of the text, schema markup defines the entities within it. Search engines do not want to guess if a string of text represents a person, a corporation, or a software product; they expect you to declare it using explicit JSON-LD scripts placed in the document <head>.
Proper entity injection relies on the BlogPosting or Article schema types. This markup must map the mainEntityOfPage to your canonical URL, identify the author as a distinct Person entity with their own validating URL, and define the publisher as an Organization. The mechanism works by feeding the search engine a direct, machine-readable graph of relationships that bypasses linguistic ambiguity entirely.
The standard mistake technical teams make is relying on automated plugins that generate disjointed schema blocks. Instead of a single, cohesive graph where the author and publisher are nested within the article object via @id references, the page outputs three separate scripts that do not communicate. The crawler sees an article, a person, and an organization on the same page, but is forced to guess how they relate.
Practical rule: Always consolidate your structured data into a single
@grapharray within one JSON-LD block, ensuring every entity references the others using shared@idvalues.
3. Aligning internal link routing with crawler priority
XML sitemaps do not transfer domain authority
Understanding the relationship between your sitemap and seo performance dictates how you route your internal links. An XML sitemap is nothing more than a discovery mechanism. It provides a list of URLs and a lastmod timestamp, serving as a suggestion to the crawler about what exists on the server. However, inclusion in a sitemap passes zero link equity and provides no contextual relevance.
Context and priority are established exclusively through the internal link graph. The mechanics involve PageRank flowing from high-authority hub pages down through contextual anchor text into deeper content. When a crawler finds a link inside a body paragraph, it uses the surrounding text to understand the target page's topic, and the internal link itself acts as a vote of confidence that justifies the crawl budget required to index it.
The critical failure mode here is the creation of orphaned pages. Teams will publish new content, verify it appears in the XML sitemap, and assume the job is done. Without hardcoded internal links pointing to that new page from existing, frequently crawled URLs, the search engine will discover the page in the sitemap but relegate it to the "Discovered - currently not indexed" queue. Operating across multiple languages often breaks manual link maps, which is why scaling requires a structured AI SEO platform for European businesses to automate contextual internal routing without generating orphaned URLs.
4. Adapting technical architecture to restrictive platforms
Rendering delays compromise indexation on managed builders
Approaching seo and wix requires abandoning server-side assumptions. Legacy managed website builders historically rely heavily on client-side JavaScript to render their visual interfaces. When a search crawler requests a page, it initially receives an empty shell; the actual text and links are only generated after the crawler executes the JavaScript bundle.
The mechanism at play is dynamic rendering. Search engines have a two-wave crawling process: the first wave grabs raw HTML, and the second, more resource-intensive wave executes JavaScript. The mistake developers make on these platforms is assuming that because text is visible in the visual editor, it is immediately accessible to the first wave of crawling. If your primary navigation links rely on JavaScript onClick events rather than standard <a href> tags, the crawler cannot follow them during the initial pass, stalling indexation. You must inspect the initial DOM load using Google Search Console's URL inspection tool to ensure your text and links are present in the raw, unrendered source code.
Infinite crawling ruins user-generated content
Managing seo for forums introduces aggressive crawl budget limitations. Unlike a standard publication where the editorial team controls every URL, forum software programmatically generates infinite pages. Every user profile, every sorting filter, every pagination layer, and every tag creates a unique URL.
The mechanical fix relies on strict parameter handling and canonicalization. You must utilize the robots.txt file to block crawlers from accessing sorting parameters (like ?sort=newest), and apply noindex directives to low-value user profile pages. The common failure occurs when administrators allow search engines to crawl every generated facet. The search bot spends its entire allotted crawl budget reading thousands of empty user profiles and duplicate pagination strings, leaving the actual, high-value discussion threads uncrawled and unindexed.
Closed ecosystems force internal routing compromises
Handling seo for google sites removes your ability to edit the document head entirely. The platform operates as a completely closed ecosystem: you cannot access the raw HTML, you cannot inject JSON-LD schema, and you cannot modify the robots.txt file.
Because you lack access to the meta-layer, the mechanism for optimization shifts entirely to manual, on-page hierarchy. You are forced to rely strictly on the text formatting native to the editor and aggressive internal linking structures. The critical mistake users make is trying to force standard technical tactics into this environment by embedding custom HTML blocks. These blocks are rendered within <iframe> tags, meaning the search engine attributes the content to the iframe source rather than your actual page. In these rigid environments, you must abandon schema entirely and focus purely on establishing a dense, heavily interlinked text hierarchy that the crawler can parse without meta-hints.
Common Pitfalls & Troubleshooting
The Visual Mirage
- Symptom: You publish a page that looks identical to a high-ranking competitor, but your page refuses to index or rank.
- Diagnosis: When troubleshooting poor indexing, marketers often realize they have copied the visual layout of an article de blog exemple without copying its underlying semantic structure. The competitor's page likely utilizes nested
<article>tags and hidden JSON-LD schema, while your replica relies entirely on generic<div>tags and CSS styling. - Fix: Audit the competitor's raw source code, not their visual template. Rebuild your document outline using strict H2 and H3 tags mapped directly to the logic of the argument, not the design.
The Frankenstein Schema Injection
- Symptom: Google Search Console reports "Unparseable structured data" or the Rich Results Test shows five different, unconnected entity types on a single page.
- Diagnosis: This occurs when multiple CMS plugins attempt to write JSON-LD simultaneously. Your SEO plugin writes an
Articleschema, your author plugin writes aPersonschema, and your theme writes aWebPageschema, none of which share@idreferences. - Fix: Disable schema generation across all secondary plugins. Centralize your structured data into a single, manually verified JSON-LD block generated by one authoritative tool.
Pagination Link Decay
- Symptom: Your older content slowly drops out of the search index over time, showing up as "Crawled - currently not indexed" in Search Console.
- Diagnosis: As new content pushes older pages deeper into the pagination structure (e.g., from page 1 to page 12 of your blog archive), the older pages lose their internal link equity. The crawler determines they are no longer important because they are too many clicks away from the homepage.
- Fix: Implement a robust related-posts module that links older, conceptually relevant pages directly from your newest content, bypassing the pagination hierarchy entirely.
FAQ
Does the order of heading tags impact indexation? Yes. Search engines rely on a strict sequential hierarchy to understand document structure. Jumping directly from an H2 to an H4 breaks the logical outline, causing the crawler to orphan the H4 content from its parent section, which dilutes the topical relevance of that section.
Can I rely on my CMS to generate schema automatically?
Only if you verify its output. Default CMS schema is often highly generic and fails to properly map the publisher or link the author to a verifiable identity graph. You must audit the automated output using a schema validator to ensure exact @id nesting.
Why is my internal link graph more important than my sitemap? An XML sitemap only tells a search engine that a URL exists on a server. An internal link provides the crawler with context via anchor text and transfers mathematical priority (PageRank) to the target page, which is the actual mechanism that dictates whether a page is worth indexing.
Should I use tags and categories to structure my content?
Categories should be used strictly to define the physical URL architecture of the site (e.g., /category/post-title/). Tags often create duplicate, thin-content archive pages that consume crawl budget without providing value. If you use tags, their archive pages must carry a noindex directive.