Structuring SEO for Website Visibility: Internal Links and Data Frameworks
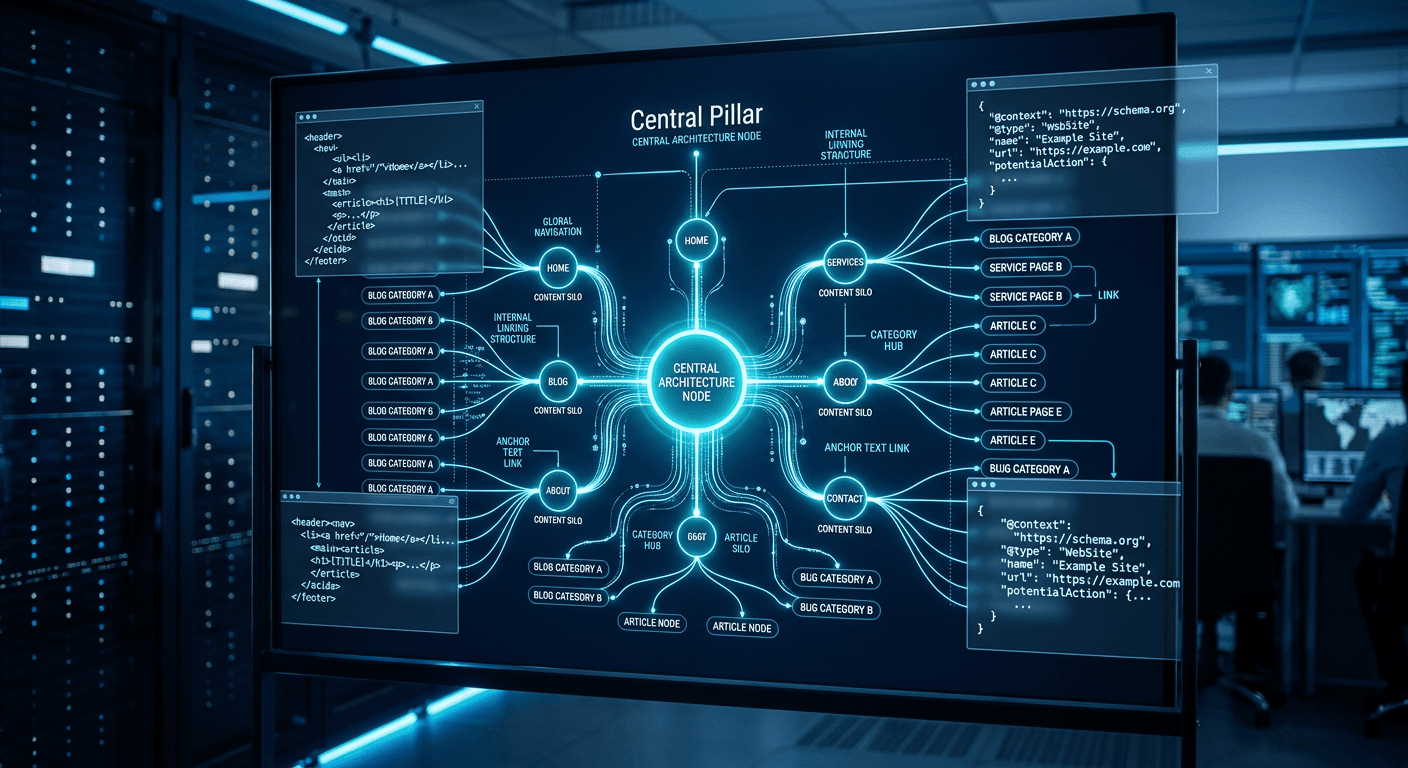
The assumption that writing great content alone is enough to capture organic traffic is the fastest way to fail at search engine optimization. Search engines do not read text the way humans do; they parse relationships, extract entities, and map context through structural signals. If a page exists without inbound links, structured data, or clear HTML semantics, it is functionally invisible to a crawler. Building effective seo for website visibility means treating your content as a database rather than a magazine. This requires engineering a deliberate internal link architecture, deploying JSON-LD schema correctly, and ensuring that various platforms - from traditional search bots to AI-driven aggregators - can understand your site's hierarchy without needing to guess. What follows is a definitive framework for structuring your site so that rendering engines process your authority exactly as you intend.
Quick Summary
Structuring content for multi-platform visibility requires shifting from keyword placement to entity relationship mapping. Search algorithms rely on explicit structural signals to calculate a page's relevance, topical depth, and hierarchical importance within the broader domain.
- Entity silos group related content physically and conceptually to build domain authority.
- Exact-match internal links pass both PageRank and definitive context to target URLs.
- JSON-LD structured data bypasses natural language processing limits by declaring facts in code.
- Semantic HTML tags dictate the document outline for both accessibility tools and rendering bots.
- Crawler access configurations ensure European consent mechanisms do not block algorithmic discovery.
Table of Contents
- 1. Establishing the seo for website entity hierarchy
- 2. Building an exact-match internal linking framework
- 3. Deploying JSON-LD structured data
- 4. Formatting semantic HTML for multi-platform parsing
- 5. Configuring crawler access limits
- Common Pitfalls & Troubleshooting
- FAQ
- Recommended Reads
1. Establishing the seo for website entity hierarchy
Content silos dictate how crawlers distribute topical authority
Before you write a single paragraph, you must map how the new page fits into the existing site architecture. Search engines measure distance. A page that requires six clicks to reach from the homepage is algorithmically deemed less important than a page accessible in two clicks. An effective hierarchy uses a hub-and-spoke model - often called content silos - where a broad, authoritative pillar page links directly to highly specific sub-topic pages, and those sub-topic pages link back to the pillar.
This architecture works because crawlers allocate a specific "crawl budget" to every site. When pages are grouped logically, the bot efficiently follows the path, passing link equity (PageRank) back and forth between related concepts. If you dump every new article into a flat /blog/ folder with no thematic categorization, the crawler has to guess which pages are foundational and which are tangential.
The most common mistake here is creating orphaned content. A marketing team publishes a highly targeted landing page, links to it once in a promotional email, but fails to add permanent navigational or contextual links from the site's existing architecture. As soon as the email campaign ends, the page is buried.
To check your current hierarchy, run a crawl using a standard SEO auditing tool and sort your pages by "crawl depth." Any critical business page that sits at a depth of four or higher needs immediate structural elevation through new parent categories or direct navigation links.
2. Building an exact-match internal linking framework
Anchor text acts as a definitive context label for search algorithms
Internal linking is not just about keeping users on your site; it is the primary mechanism for distributing SEO for site relevance. When one page links to another, the text used in that link (the anchor text) acts as a label. If Page A links to Page B using the phrase "enterprise firewall configuration," the algorithm applies that exact phrase as context for Page B.
This mechanism relies on precision. The algorithm reads the anchor text and the words immediately surrounding it to assess the destination's subject matter. If you consistently use generic phrases like "read more" or "click here," you are wasting the strongest relevance signal you control.
Practical rule: Never use a specific target keyword as anchor text if it points to a page that is not the primary ranking target for that term; you will cannibalize your own site's authority.
The frequent failure point in internal link architecture is the "First Link Priority" rule. When a crawler finds two links pointing to the same destination on a single page, it generally only counts the anchor text of the first link it encounters in the HTML. If your main navigation links to your services page with the anchor "Services," but you later link to it in the body text with the highly optimized anchor "cloud server hosting," the crawler prioritizes the generic "Services" anchor.
To act on this today, audit your top five highest-traffic pages. Identify three structurally related pages that are currently underperforming, and insert deliberate, keyword-rich internal links from the high-traffic pages directly to the underperforming ones.
3. Deploying JSON-LD structured data
Schema deployment bypasses the limits of natural language processing
No matter how clearly you write, natural language processing involves algorithmic guesswork. Structured data removes the guesswork. By injecting JSON-LD (JavaScript Object Notation for Linked Data) into the <head> or <body> of your HTML, you hand the crawler a machine-readable dictionary of facts about the page.
When optimizing seo in site architectures, JSON-LD allows you to explicitly define relationships using @id nodes. You can state definitively that the page is an Article, written by a specific Person, published by a specific Organization, and that it answers a specific FAQPage schema. This code does not change the visual presentation of the page; it exists purely for the machines. It is the mechanism that generates rich snippets - like review stars, pricing carousels, and explicit author knowledge panels - in search results.
The critical error developers make is deploying structured data dynamically via heavy client-side JavaScript without a server-side fallback. If the schema relies on an external script to execute, and the search bot's render budget expires before the script loads, the bot will index the page as having no structured data at all.
Test your deployment immediately by pasting a URL into the official Schema.org Validator. Ensure that your Organization and WebPage entities are nested correctly, rather than floating as disconnected nodes.
4. Formatting semantic HTML for multi-platform parsing
Bot rendering engines rely on strict heading outlines to index meaning
An SEO website framework must communicate its structure through semantic HTML. Tags like <header>, <nav>, <main>, <article>, and nested heading tags (<h1> through <h6>) form a standardized Document Object Model (DOM) tree. Both traditional search bots and modern AI-driven aggregators rely on this tree to differentiate the core content from the boilerplate navigation and footer.
Heading tags are not styling tools; they are structural boundaries. When a crawler sees an <h2>, it assumes everything below it belongs to that topic until it encounters the next <h2>. If you drop an <h3> under that section, the crawler understands it as a sub-topic. This outlining mechanism dictates how algorithms generate automated table of contents links and featured snippets.
The mistake publishers make is allowing designers to use heading tags purely for visual sizing. If a designer uses an <h3> for a stylized quote block directly below an <h1> because they liked the font size, they have broken the semantic outline. The crawler now attempts to index that quote as a major sub-topic, confusing the page's relevance.
To fix this, disable CSS on your most important landing page or run it through an HTML5 Outliner tool. If the resulting text does not read logically like a university textbook's table of contents, your semantic structure is broken and needs immediate recoding.
5. Configuring crawler access limits
European consent walls frequently block technical bot discovery
Technical structure is useless if the rendering bot is legally or technically barred from reading it. In regions governed by GDPR, websites employ strict Consent Management Platforms (CMPs) that block non-essential scripts and cookies until the user clicks "Accept." Search bots do not click buttons.
If your platform is configured to block the loading of the primary DOM until consent is registered, the bot simply crawls a blank page with a popup modal. To resolve this, server infrastructure must identify known crawler User-Agents (like Googlebot or Bingbot) and serve them the fully rendered, stateless HTML document without triggering the interactive consent modal, while simultaneously ensuring no tracking scripts fire during the bot's visit.
Reviewing how platforms manage automated AI-Driven SEO for European Businesses offers a baseline for balancing bot access with strict data privacy. The failure mode here is accidental cloaking. If your server identifies a bot and serves it a completely different, highly optimized HTML file than what a human would see if they bypassed the consent wall, search engines classify this as deceptive cloaking and will issue a manual penalty, removing the site from the index.
You can verify your configuration today by using the "Test Live URL" feature in Google Search Console. View the rendered HTML tab to confirm that the bot sees your full article text, your internal links, and your JSON-LD, rather than a string of JavaScript demanding cookie consent.
Common Pitfalls & Troubleshooting
Even when the theory is understood, deployment often fractures. These are the three structural failures that look identical from the outside but require completely different diagnostic repairs.
1. The Infinite Pagination Black Hole
- Symptom: Deep historical articles or older e-commerce products suddenly stop receiving impressions, despite remaining live and indexed.
- Diagnosis: The site relies entirely on standard numbered pagination (Page 1, Page 2, Page 3...) to link to older content. As new content pushes older pages deeper into the pagination sequence, they exceed the crawler's depth limit and are dropped from active memory.
- Fix: Implement a robust HTML sitemap and build lateral internal links. Whenever a new article is published, manually link it backward to 2-3 older, relevant articles, pulling them out of the pagination depths and back into the primary crawl path. This is the most frequent cause of "decaying" traffic.
2. Cannibalized Anchor Text Focus
- Symptom: Three different pages on your domain are bouncing between positions 15 and 50 for the same high-value keyword, changing places every week.
- Diagnosis: You have used the exact same target keyword as an internal link anchor pointing to three different URLs. The search engine cannot determine which page is the definitive answer, so it rotates them, dividing your domain's authority.
- Fix: Choose the single most comprehensive page as the primary target. Run a site search for the keyword, find the conflicting internal links, and update their anchor text or redirect them to point exclusively to the chosen primary page.
3. The JavaScript Schema Trap
- Symptom: Your structured data passes perfectly in third-party validation tools, but Google Search Console reports zero rich results or valid schema entities.
- Diagnosis: The validation tool waits patiently for your client-side JavaScript to render the JSON-LD, but the actual Googlebot abandoned the page before the scripts finished executing due to a tight render budget.
- Fix: Move schema generation to the server side. Ensure the JSON-LD block is hard-coded into the initial HTML response delivered by the server, requiring zero client-side processing to become visible.
FAQ
Does the physical URL structure matter if internal linking is strong?
Yes, but its importance is secondary to link architecture. A clean directory structure (e.g., /services/financial/audit/) helps bots understand hierarchy instantaneously and allows for easy segment tracking in analytics. However, a flat URL structure (where everything sits at the root domain) can still rank perfectly if the internal linking and semantic HTML define the relationships clearly.
Should I use Microdata instead of JSON-LD for older platforms? No. JSON-LD is the explicitly recommended format by every major search engine. Microdata requires wrapping your visible HTML tags in schema vocabulary, which drastically increases the risk of breaking your visual layout or creating syntax errors when updating content. JSON-LD separates the data from the design entirely.
How many internal links are too many on a single page? There is no absolute numerical limit, but PageRank is divided by the number of outbound links on a page. If a page has 10 internal links, each receives a larger share of authority than if the page had 200 links. Keep internal links limited to genuine, contextually relevant connections rather than building exhaustive link walls.
Do breadcrumbs count as internal links for SEO? Yes. Breadcrumb navigation provides a consistent, automated internal linking structure that reinforces the site's vertical hierarchy. Furthermore, when combined with BreadcrumbList structured data, they allow search engines to display your site's directory path directly in the search results, improving user click-through rates.